Most guides on author E-E-A-T say "add an author bio." None show the schema behind it, or explain why a bio without structured data sends only half the signal. This page is the other half: the real Person JSON-LD from a live blog, the specific changes that completed the author entity, and the one pattern most implementations miss — linking articles by @id instead of redefining the author on every post.
The short version: Google does not penalise AI content for being AI — it rewards real, verified authorship as a trust signal. Below: why author E-E-A-T exists, what it looks like in practice on a real blog with the actual schema code, and the one @id pattern that separates a complete author entity from a partial one.
Does Google penalize AI content?
No — and this is policy, not inference. Google's guidance rewards quality "however it is produced" and reserves penalties for spam behaviors: scaled content abuse, site reputation abuse, link schemes. The method-agnostic wording matters. A human content farm pumping out 500 thin pages violates the same policy as an AI doing it. One person publishing a carefully edited AI-assisted article violates nothing.
What changed in the last two years is enforcement scale, not principle. Sites that flooded the index with low-effort AI pages lost visibility not because Google smelled the model — but because the pages were the same low-value inventory the policy always targeted, now produced faster.
Does Google know if content is AI-generated?
It does not need to, and that is the part most people miss. Google's systems evaluate what they can measure: does the page add anything beyond what already ranks, do its claims hold up, does it show first-hand experience, do readers stay or bounce back to the results. Unedited AI output fails those measurements on its own — no detector required. Which also means the inverse: passing an "AI detection" check does nothing for rankings if the page is still hollow. Chasing detector scores instead of quality is optimizing the wrong variable.
What actually gets AI pages demoted
- Thin repetition. The page restates the current top ten without adding a fact, example, or position they lack.
- Zero experience. Nothing on the page required the author to have done anything. E-E-A-T's first E is the one AI cannot fake.
- Unverified claims. Models state falsehoods with full confidence, and a single wrong statistic can undermine everything else on the page.
- The AI voice. Uniform rhythm and watermark words signal "generated and unedited" to readers — the tells are countable — and reader behavior feeds back into rankings.
What does author E-E-A-T look like in practice?
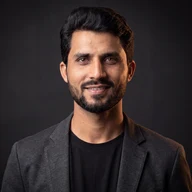
Until September 25, 2026, every post on this blog showed the company logo as the author avatar. The schema said "Skryvo Team." That is the most common author E-E-A-T gap: a brand in the author slot where a person should be. Here is what the retrofit looked like, across two sessions.
The five changes:
- A real author photo. The company logo was replaced with a real photo at three resolutions (96/192/384px webp). The schema and the byline now show the same person.
- A single Person entity with a shared
@id. One canonical identifier (https://skryvo.ai/#person-muhammad-shakil) defined once in the codebase. Every article references it by@idinstead of redefining it — so the whole site resolves to one author node. - Verifiable identity links.
sameAspoints to the LinkedIn and X profiles where the same person is findable under the same name. - Primary sources linked. Claims cite the policy, the paper, or the documentation — not a blog citing a blog.
- Visible maintenance. Updated dates on the page and in schema, because facts expire and freshness is a trust signal.
The Person schema as it ships on this site, September 25, 2026:
{
                    "@type": "Person",
                    "@id": "https://skryvo.ai/#person-muhammad-shakil",
                    "name": "Muhammad Shakil",
                    "jobTitle": "Founder",
                    "url": "https://skryvo.ai/about/",
                    "image": "https://skryvo.ai/assets/images/author-muhammad-shakil-384.webp",
                    "sameAs": [
                      "https://www.linkedin.com/in/flutterdeveloper1/",
                      "https://x.com/MShakilAwan3",
                      "https://flutterstudio.dev/"
                    ],
                    "knowsAbout": [
                      "AI content generation",
                      "Fact-checking",
                      "Search engine optimization",
                      "Flutter",
                      "Software engineering"
                    ]
                  }
The part most plugin guides miss: every article references this entity with "author": {"@id": "https://skryvo.ai/#person-muhammad-shakil"} — a pointer, not a copy. Google walks the @id graph and assembles one authoritative Person node across all references. Ten posts pointing at one @id build a stronger entity than ten posts each defining their author from scratch.
These signals exist because Google's quality guidelines treat experience, expertise, authoritativeness, and trust as properties of the person behind the content, not the brand. Structured authorship is how a page carries that signal in a form Google can parse unambiguously. Whether these changes improve rankings on this site is not yet known — they went live September 25, 2026, and search results take weeks to reflect changes.
A workflow that ranks
- Start from search intent, not a keyword. Outline against the real questions people type — then generate.
- Fact-check before you polish. There is no point perfecting a sentence that is wrong.
- Add what only you can add. One real number, screenshot, or scar from your own work lifts the page above every generic competitor.
- Edit for a human voice. Read it aloud; fix what sounds generated.
- Score, then publish. In Skryvo every draft ships with a fact-check pass and a quality score you can audit claim by claim — the gate is the workflow, not an afterthought.
AI does not disqualify your content, and it will not rank it either. The policy is public, the bar is knowable, and the work above is a day, not a quarter. Do the work. Sign your name to it. Let the content farms keep testing Google's patience for you.
Write content you can publish with confidence
Skryvo generates, fact-checks, and scores your content — try it free.